
DeepSeek V4.1 Flash vs Claude Opus 5: the 33.3x Input Gap Is Only Half the Story
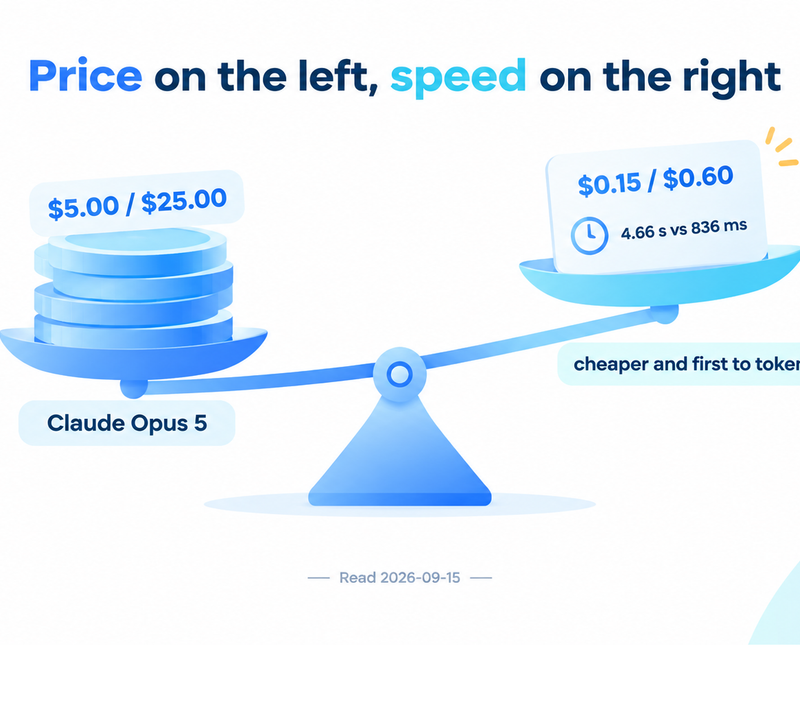
Teams usually meet a frontier model through its subscription page, where the pricing question has already been answered for them: a flat monthly fee, a character limit, a file upload size. Move the same decision to an API and the flat fee disappears, replaced by two numbers per million tokens that most teams multiply badly. OrcaRouter hosts both ends of that spectrum — Claude Opus 5 at $5.00 per million input tokens and $25.00 per million output, and a model at $0.15 in and $0.60 out that is the fastest to its first token in our telemetry: deepseek v4.1 flash price is where the arithmetic starts, and it is a different kind of arithmetic.
All prices and latency figures read 2026-09-15.
The price gap, computed from published rates
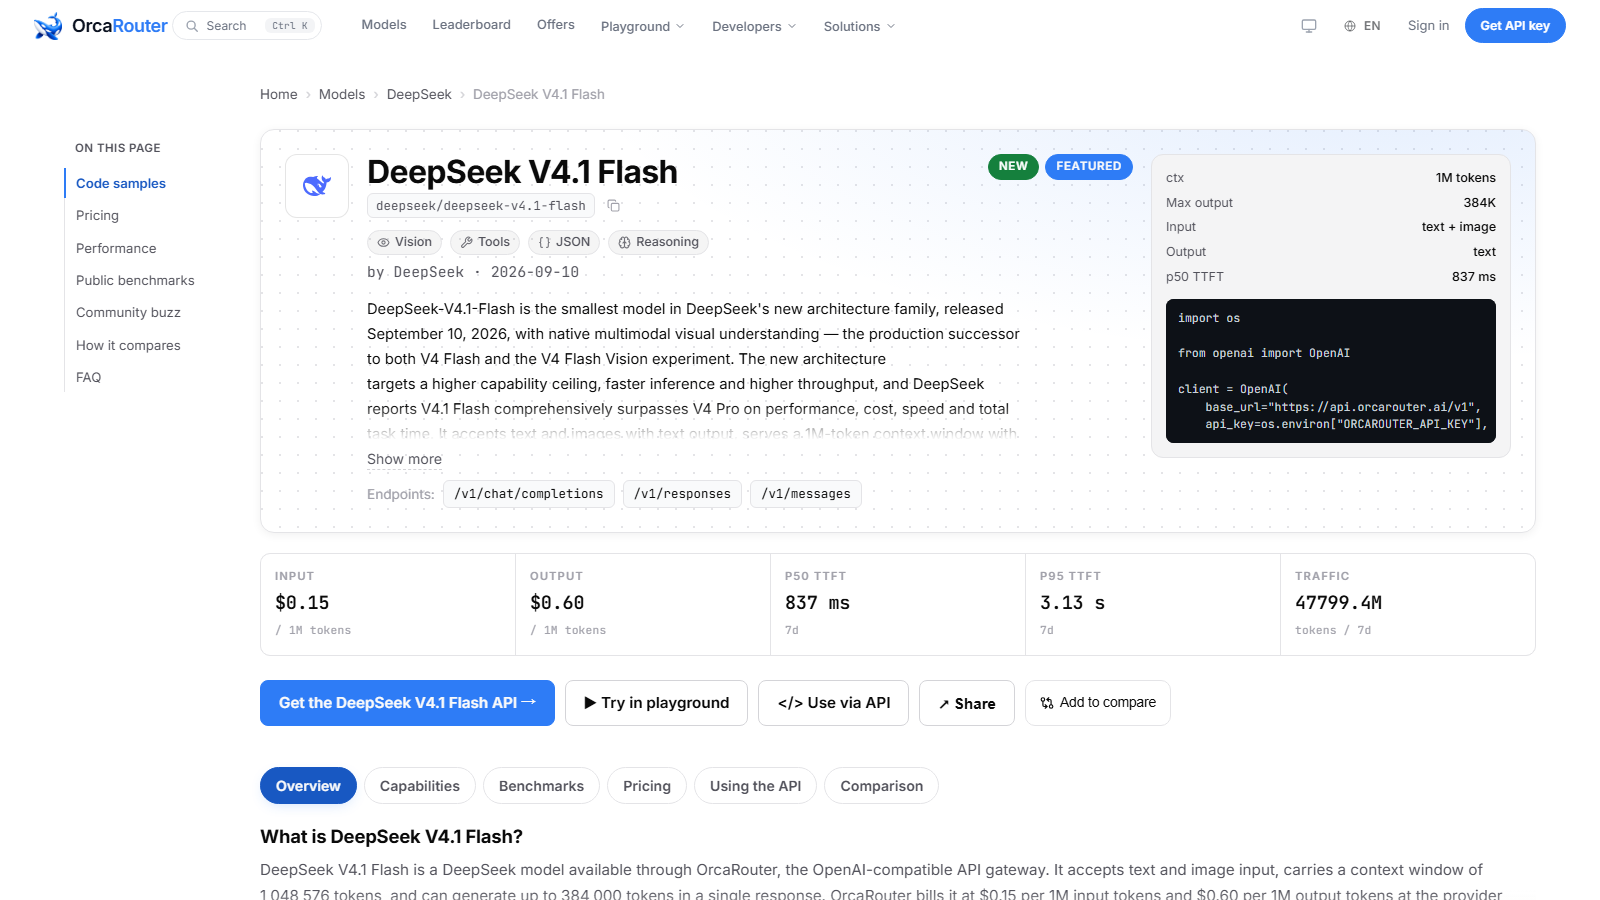
DeepSeek’s official pricing page, read 2026-09-15, lists `deepseek-flash` — the canonical name for V4.1 Flash — at $0.15 per million input tokens and $0.60 per million output tokens off-peak. Claude Opus 5’s published list of $5.00 in and $25.00 out puts the gap at 33.3x on input and 41.7x on output. The second multiple matters more than the first, because output is where generation happens: an assistant answering user questions, an agent writing tool results into a plan, a summarizer emitting most of its tokens as text. Every token that gets written to the screen is billed at the steeper end, and on long completions the 41.7x multiple compounds with every sentence.
Two adjustments keep the comparison honest. The DeepSeek column is the off-peak rate; peak hours are 01:00–04:00 and 06:00–10:00 UTC, Monday through Friday, which is 35 hours out of the 168-hour week. That leaves 79.2% of all hours off-peak, weekends entirely, so most interactive traffic lands on the cheap side of the ledger — but a cron job that runs at 01:00 UTC pays double for the same request, and that is exactly the kind of footnote a cost model needs to carry. And the cache lines change the picture further: V4.1 Flash’s cache-hit input price is $0.003 per million tokens off-peak, a 50x discount off the miss price per DeepSeek’s own page, which makes repeated system prompts and long context blocks nearly free. On a conversational workload where the same instructions ride along on every call, the effective input price collapses.
The first-token gap, measured on one platform
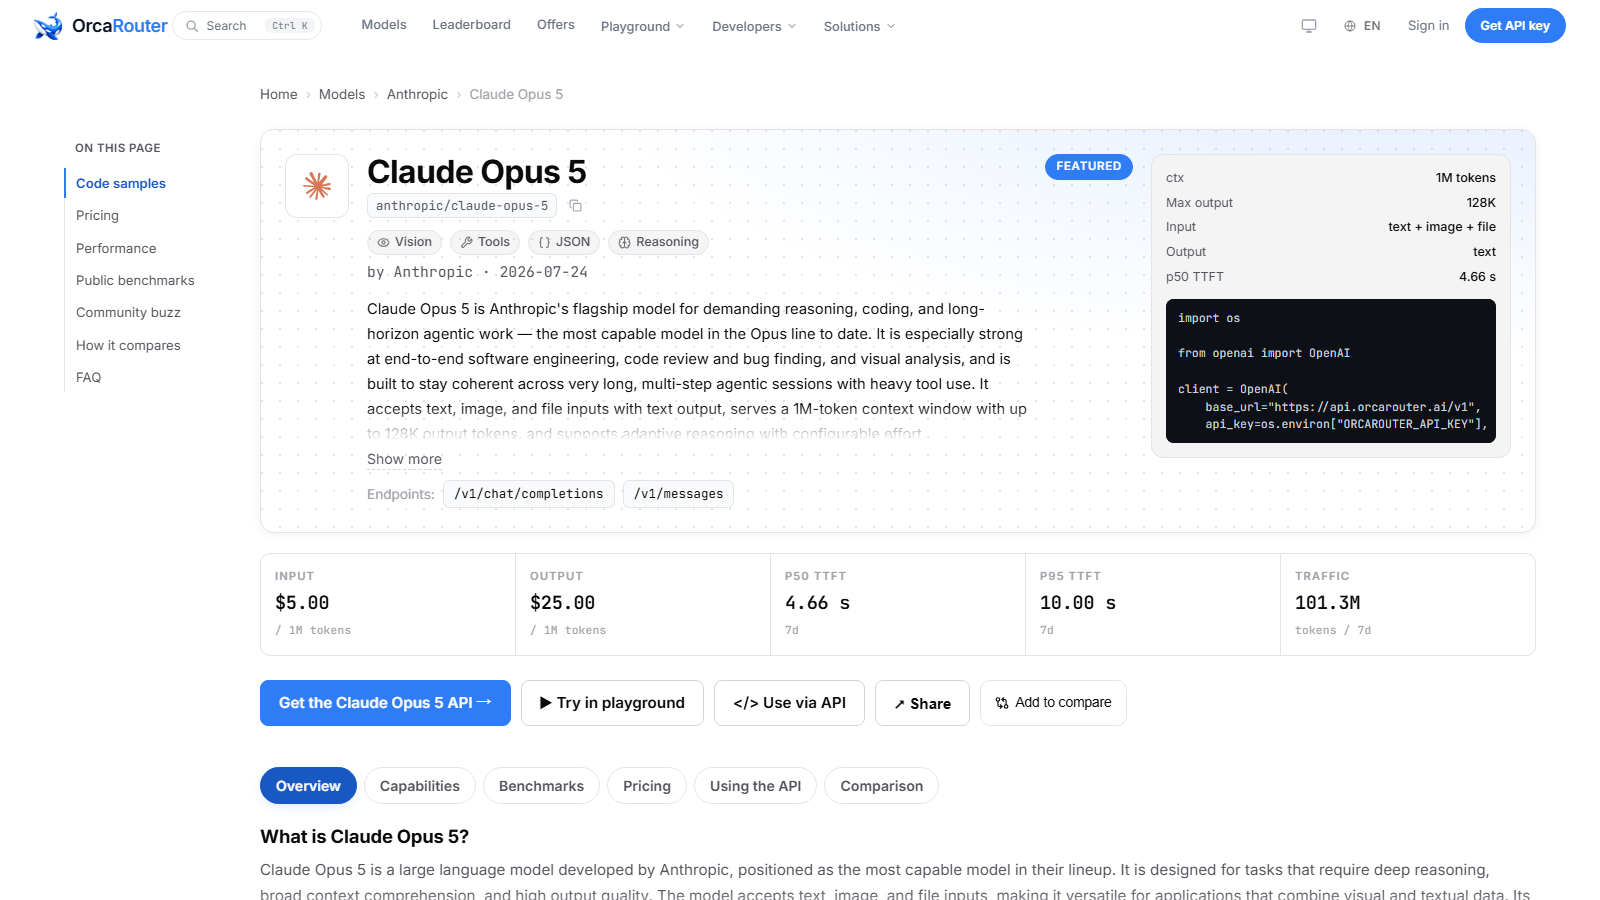
The price columns answer what a request costs, and the latency column answers when it starts answering — a different axis that changes the feel of a product more than the bill does. Our production telemetry, a 7-day rolling window read 2026-09-15, puts V4.1 Flash’s median time to first token at 836 ms and Claude Opus 5’s at 4.66 s. That is a 5.6x difference on the first-token axis, and it means the cheaper model also opens its answer while the user is still finishing the sentence that prompted it.
These figures are real observations, not a controlled benchmark: they reflect one platform’s traffic mix, regions and live provider load, and the decimals drift daily. But the ordering has been stable across the window, and the consequence is straightforward. At 4.66 seconds a chat request registers as a pause before every answer; at 836 milliseconds it registers as instant. For batch pipelines the latency column barely matters. For anything with a human waiting on the response — a chatbot, a copilot, an inline assistant — it is the difference between a tool that feels live and one that feels like it is deliberating, and products are bought and abandoned on exactly that difference.
Which workload each model actually wins
A fair comparison has to concede the frontier case, because it is real. Claude Opus 5 is the model to reach for when the request is hard and the answer is expensive to get wrong: long-horizon reasoning, complex tool chains, safety-sensitive generation where a failure costs more than any multiple of the token bill. Our telemetry shows a usage pattern that matches: Claude Opus 5 carried 101.3M tokens over the seven-day window against V4.1 Flash’s 47,198.3M. Teams are not wrong to spend that way — they are sending a small number of heavy, careful requests to the frontier model and a vast stream of interactive ones to the flash model. The two choices serve different jobs, and the numbers reflect that division of labour rather than any quality ranking.
V4.1 Flash’s territory is the stream. It posts the fastest median first token in our telemetry table. It adds native vision — DeepSeek’s official feature table marks it supported, where the same table lists V4 Pro as not supporting vision — a 1M context window and a 384K maximum output. Its DeepSeek-published benchmarks are all vendor-reported, which is the right way to read them, and they are strongest on the agentic and coding rows: Terminal-Bench 2.1 at 90.6, DeepSWE v1.1 at 74.2, CyberGym at 88.1. At a third of a cent of input per call off-peak with cache hits, it is cheap enough to call per user without a cost review — the economic shape of chat, agents and copilots.
The mistake is to force a winner. The useful question is cost-per-outcome: if you run both models against your own eval set and the frontier model moves a metric that matters — acceptance, correctness on a labeled set, task completion — then paying the multiple is a sound business decision. If it does not, you are paying 33.3x on input and 41.7x on output for a benchmark row your traffic never touches.
What a reproducible comparison requires
Keep the comparison comparable. Use the canonical model names on the day you quote them — `deepseek-flash` for V4.1 Flash — and state which price tier you are quoting, because the peak window doubles the DeepSeek figure and most write-ups quote only the off-peak number without saying so. Measure cost per task, not cost per call: a request that sends 5,000 tokens of context and receives 500 tokens of output bills differently from one that sends 500 and receives 5,000, and the output-heavy shape lands on the steeper 41.7x multiple. And treat the latency column as telemetry rather than a guarantee: it is a 7-day rolling median that drifts, while the ordering between the two models has been stable.
The takeaway
The price gap between these two models is 33.3x on input and 41.7x on output, computed from published rates read the same day, and the first-token gap runs the other way — 836 ms against 4.66 s from our own production telemetry. For the interactive, high-volume tail of your traffic, V4.1 Flash wins on price, on first token, and on cache economics. For the small set of requests where a wrong answer is the expensive outcome, Claude Opus 5 earns its premium. The two models are tiers, not competitors, and the job is to route each request to the tier that fits it instead of defaulting everything to the most expensive name on the page.
Sourcing note: DeepSeek’s prices, peak/off-peak schedule and cache discounts come from DeepSeek’s official pricing page, read 2026-09-15 (vendor-published). Claude Opus 5’s list price is the rate published on our catalog for that model, read the same day (vendor-published). The 33.3x and 41.7x gaps are arithmetic on those two published rates. All latency and traffic figures are OrcaRouter’s own production telemetry — a 7-day rolling window, read 2026-09-15, reflecting one platform’s traffic mix, regions and live provider load rather than a controlled benchmark. The DeepSeek benchmark scores mentioned are all vendor-reported, from DeepSeek’s release materials; no independent benchmark results are cited in this piece.